A zero-results page shows a shopper nothing. A dead-end conversation shows them nothing after they've told you exactly what they want.
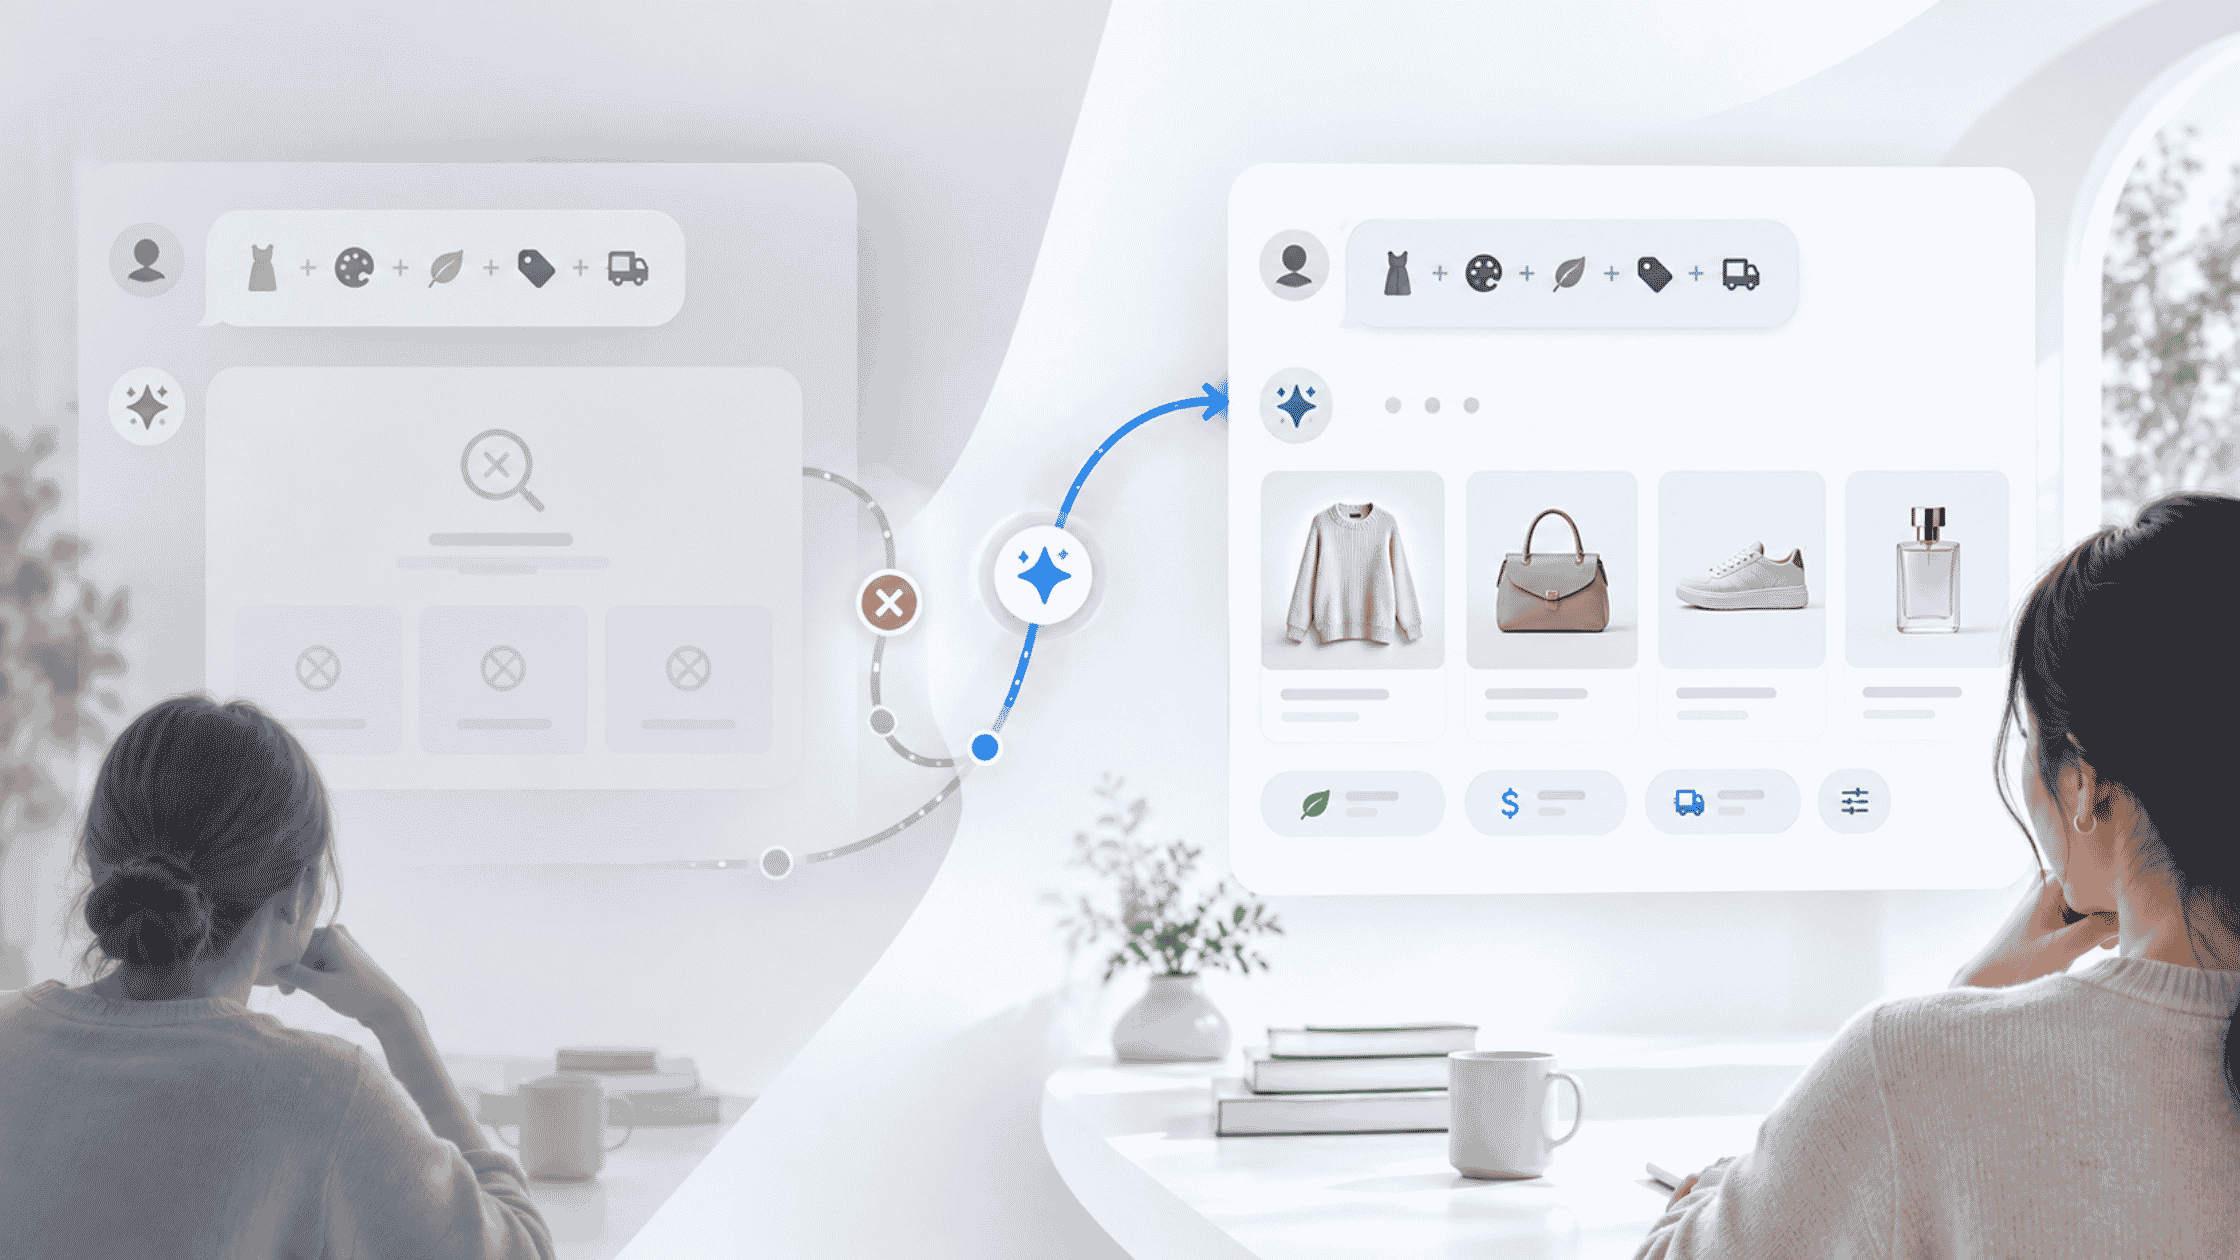
A dead-end conversation is a shopping conversation that ends with no relevant product shown: the AI assistant returns nothing, returns something irrelevant, or says it couldn't find a match. It is the conversational version of the ecommerce zero-results page, and it hits shoppers at their moment of highest intent.
Dead ends trace to four root causes: product data that describes the product rather than the need, situational requests the catalog can't map, stacked constraints with no relaxation, and stale inventory. Fix them by diagnosing failed requests, enriching and grounding catalog data, relaxing constraints transparently, and designing recovery that asks before it guesses.
What is a dead-end conversation in AI shopping?
Conversational shopping was supposed to end the zero-results page. Instead of guessing the right keyword, a shopper describes what they need in plain language and an AI shopping assistant walks them to it. But assistants have their own version of the same failure. The shopper types a precise request and gets back nothing, something irrelevant, or the line every merchandiser dreads: “I couldn't find anything matching that.”
That is a worse moment than a blank search page. The shopper invested more effort, shared more intent and got the same result. And the traffic arriving at AI shopping experiences is unusually valuable. Adobe Digital Insights' Q3 2026 AI Traffic Trends Report found that AI-referred retail visitors converted at a 54% higher rate than other traffic and generated 53% more revenue per visit in May 2026. When an assistant dead-ends one of those shoppers, you lose a disproportionate share of revenue, not an average visit.
The cost of failed discovery is well documented on the search side. A Harris Poll commissioned by Google Cloud found that 81% of US shoppers are more likely to leave a site after an unsuccessful search, and estimated that search abandonment costs retailers more than $2 trillion a year worldwide. Baymard Institute's usability research found that 68% of ecommerce sites implement their no-results page as an effective dead end, offering little beyond generic search tips. A conversational assistant that ends a chat empty-handed repeats that mistake in the one channel where the shopper handed you their exact intent.
A dead end isn't a technology limitation you have to accept. It is almost always a symptom of something specific and fixable: missing product attributes, a request the catalog can't interpret, logic that treats every preference as absolute, or inventory data that's out of date.
How is a dead end different from a zero-results page?
A zero-results page comes from keyword search that can't match the index. A dead-end conversation comes from an assistant that can't map a shopper's need, or the full set of constraints they've stated, to the catalog. The failure unique to AI is the confidently wrong answer, which a blank search page can never produce.
| Dimension | Site search | AI shopping assistant |
|---|---|---|
| Trigger | A keyword doesn't match the index | A need or constraint can't be mapped or met |
| What the shopper sees | A blank no-results page | “I couldn't find anything,” or irrelevant items |
| Typical causes | Typos, synonyms, keyword-matching architecture | Unstructured attributes, unmapped needs, no relaxation, stale stock |
| Worst variant | Irrelevant results | A confidently wrong, invented answer |
| Recovery lever | Redirects and recommendations | Clarifying questions, labeled alternatives, memory |
| Primary metric | Zero-results rate | Dead-end rate |
Site search teams have spent a decade fixing zero results with typo tolerance, synonym lists and query relaxation. Conversational assistants solve some of those problems for free, because a language model handles misspellings and synonyms naturally. But they introduce new ones. Conversations accumulate constraints, shoppers describe situations instead of products, and a model that can't find an answer may be tempted to invent one.
Why do AI shopping conversations dead-end? The four root causes
Before you fix anything, identify which problem you're actually solving. Dead-end conversations have four distinct root causes, and the treatment for each is different.
1. Product data that describes the product, not the need
Most catalogs are written for browsing: a title, a price, a paragraph of marketing copy and some variant options. Shoppers talking to an assistant ask about properties that live nowhere in that structure. Is this jacket actually waterproof or only water-resistant? Will it fit a wide foot? Is it safe for sensitive skin?
If “waterproof” appears once in the description and never as a structured attribute, the assistant can't reliably filter on it. Baymard Institute's search benchmark of leading US ecommerce sites found that 84% don't handle queries built on subjective qualifiers such as “cheap” or “high quality.” The assistant isn't failing here. The data is, and no retrieval layer can match on an attribute the catalog never captured.
2. Situational requests the catalog can't map
Search-bar shoppers type product nouns. Assistant shoppers describe situations: “something for my dad who just started golfing,” “an outfit for a beach wedding in October,” “a moisturizer that won't make me break out under makeup.”
Catalogs are organized by product type, not by occasion, recipient or problem. Baymard found that 60% of sites don't support thematic queries such as “spring jacket,” and Criteo's 2026 research found that 56% of shoppers want recommendations that go beyond exact matches for what they searched. Without a layer that translates a situation into product attributes, the assistant has nothing to match against, even when the catalog holds five perfect options.
Voice makes this sharper. A shopper speaking to a store talks the way they would to a sales associate, in full situations rather than keywords, so an assistant without a translation layer dead-ends even faster.
3. Stacked constraints with no relaxation
Conversations accumulate constraints in a way search queries rarely do. Across three messages a shopper narrows to linen, navy, size 14, under $80 and delivered before Friday. Each constraint is reasonable. Together they can intersect to zero.
Constraint relaxation is the practice of loosening the least important constraint when the full set returns nothing, rather than ending the conversation. Without it, the assistant punishes the shoppers who are most helpful about what they want. The same shopper would often happily take dark indigo, or pay $86.
4. Inventory data that's out of date
An assistant running on a stale product feed recommends something that sold out yesterday, or knows the item is unavailable and quietly drops it without offering what's next. Both end the conversation. The first breaks trust at checkout. The second hides a near-identical alternative, a restock date or another size.
The stakes are real. Stockouts are estimated to account for roughly 40% of lost sales, and one 2025 consumer study found that 55% of shoppers won't return to a site after repeated stockout experiences, both cited in Alhena's analysis of live inventory for AI agents.
What failure is worse than a dead end?
A dead end costs you a sale. A confidently wrong answer costs you the sale, a return and often the customer.
When an assistant asserts an attribute the product doesn't have, the shopper buys, the product arrives wrong and they send it back. Around 14% of returns are attributed to inaccurate item descriptions, according to Capital One Shopping, and Akeneo's 2025 Consumer Returns Report found that 43% of consumers had returned a product after pre-purchase information proved incorrect. Rithum's 2026 survey of more than 1,000 US and UK shoppers found that 58% blame the retailer or brand when an AI recommendation contains incorrect product information, and 16% would avoid the purchase entirely.
General-purpose models make the risk concrete. In Alhena's testing, ChatGPT answered standard product queries with roughly 64% accuracy and multi-constraint queries with about 52%, which means nearly half of complex recommendations missed.
Guesses to keep talking
A shopper asks whether a moisturizer is fragrance-free. The assistant has no ingredient data for it, but answers anyway.
“Yes, this one is fragrance-free.” It isn't. The sale becomes a return.
Answers only what it can verify
Same question, same gap in the data. The assistant says what it can't confirm and routes to what it can.
“I can't confirm that one. These three are fragrance-free, verified from their ingredient lists.”
This is why every effort to reduce dead ends has to be measured against accuracy at the same time. The easiest way to eliminate dead ends is to let the assistant guess. A dead end is recoverable. A confidently wrong answer usually isn't.
Step 1: How do you diagnose dead-end conversations?
Many teams skip diagnosis and go straight to implementation, which is how they end up fixing the wrong layer. Pull 30 days of shopping conversations and isolate the ones that ended with no product shown, or with products the shopper ignored. Then track three things.
- Dead-end rate. The share of shopping conversations that end with no relevant product shown.
- Failed requests by frequency. The exact phrasings that dead-end, ranked by volume. A request that fails 200 times a week is costing revenue every day it stays unaddressed.
- Active constraints at failure. How many preferences were stacked at the moment each conversation collapsed.
Then categorize your top 20 failing requests by hand. For each one, mark a single cause:
- The right product doesn't exist
- It exists but lacks the attribute asked about
- The request was situational and never translated
- It matched until constraints stacked to zero
- It matched but was out of stock, with no alternative
Most teams discover that far more of their “we don't carry that” failures are really “we carry it and never described it” failures. That distinction decides whether you need a merchandising project or an engineering one.
Keep the list of things shoppers asked for that you genuinely don't carry. Shoppers tell an assistant things they would never type into a search bar, which makes that list merchandising and product-development intelligence you can't get anywhere else.
Step 2: How do you prevent dead ends?
Prevention means an assistant that finds something relevant rather than ending the chat. Which fixes matter most depends on what your diagnosis revealed.
| Root cause | What the shopper experiences | The fix |
|---|---|---|
| Unstructured attributes | “No waterproof jackets found” when you stock six | Enrich structured attributes from failed requests |
| Unmapped situations | Generic bestsellers, or nothing, for a gift or occasion | Add a need-to-attribute translation layer |
| Constraint stacking | Zero results after adding one more preference | Relax the weakest constraint and say so |
| Stale inventory | The recommended item is sold out at checkout | Sync live, variant-level stock |
| Invented attributes | A confident claim the product doesn't support | Ground every claim in verified catalog data |
- Enrich attributes from what shoppers actually ask. Don't audit the whole catalog. Your failed-request log is a free enrichment backlog. Take the attributes that appear most often, such as fit, material, use case, compatibility and ingredient exclusions, and make them structured fields. Much of this can be extracted from existing descriptions, reviews and size guides.
- Build a need-to-attribute translation layer. “Beach wedding in October” should resolve to lightweight fabrics, dressy-casual styling and seasonal colors. “Won't break me out” should resolve to non-comedogenic and fragrance-free. This layer is what separates a shopping assistant from a search bar with a chat window.
- Relax the weakest constraint, and say so. When a combination returns nothing, loosen the least important constraint and tell the shopper what changed. Transparent relaxation converts. Silent substitution feels like being ignored.
- Sync live inventory at the variant level. Every size, color and SKU should be current, so the assistant never recommends something the shopper can't buy and can offer the closest in-stock option instantly.
- Ground every claim in the catalog. An assistant that only asserts attributes it can verify can be tuned aggressively for coverage without the risk of fabrication. That is what makes it safe to push the dead-end rate down.
Step 3: How do you recover from a dead end?
Even a well-tuned assistant will hit genuine dead ends: products you don't carry, requests too vague to act on, edge cases. What it does next decides whether the session survives.
- Ask before you guess. “I need a gift” shouldn't produce a generic bestseller list. One or two clarifying questions about who it's for, what they're into and a rough budget turn an unanswerable request into a narrow, high-converting one. This is the biggest advantage a conversation has over a search bar, and most assistants under-use it.
- Be honest about the miss. “We don't carry trail running shoes in wide sizes” beats a list of road shoes presented as if they matched. Shoppers who get a straight answer keep talking.
- Offer the nearest real alternative, labeled as one. Show what's closest and explain the difference: “These run slightly narrow, but the same model comes in a wide version.” The label is what makes it helpful rather than evasive.
- Keep the conversation's memory. When a shopper refines a request, keep every earlier preference except the one that changed. Making someone restate their size and budget after a dead end is how you lose them on the second attempt.
- Capture intent you can't serve yet. Offer a back-in-stock alert, a new-arrivals notification or an email with close matches. A dead end with an opt-in is a future sale. A dead end without one is a lost customer.
Not every request needs a question. A precise request such as “black leather Chelsea boots, size 10” should get products immediately. The skill is knowing when a request is specific enough to answer, and when one question will produce a far better result.
How do you measure dead-end conversations?
Fixing dead ends is a process, not a one-time project. Your primary metric is the dead-end rate.
Dead-end rate = (shopping conversations ending with no relevant product shown ÷ total shopping conversations) × 100
Establish a weekly baseline before changing anything. No cross-industry benchmark for conversational assistants has been published yet, so measure against your own trend line. Site-search zero-result rates of 12–20% are a useful upper reference: if your assistant dead-ends more often than your search bar returns nothing, the assistant is adding friction rather than removing it.
| Metric | How to calculate it | What it tells you |
|---|---|---|
| Dead-end rate | No-product conversations ÷ all shopping conversations × 100 | How often discovery fails outright |
| Recommendation engagement | Recommendations clicked or added to cart ÷ recommendations shown | Whether you show the right products, not just any products |
| Assisted conversion | Shopping conversations ending in a purchase ÷ all shopping conversations | The number that justifies the assistant |
| Recommended-item returns | Returns on assistant-recommended purchases ÷ those purchases | Whether dead ends are being traded for wrong answers |
| Recovery rate | Dead-end conversations that still reach a click or purchase ÷ all dead ends | Whether your Step 3 recovery design works |
Tag every change with its implementation date and compare the following two to four weeks. If dead ends fall while returns on recommended items rise, the assistant has started guessing.
One practical note: all of this requires conversation-level analytics that record what was asked, what was shown and what was clicked. If you can only see aggregate chat volume, fix that first.
What product data does an AI shopping assistant actually need?
Beyond titles, prices and variants, an assistant needs structured attributes that match how shoppers describe their needs.
- Materials and fabric
- Fit and sizing guidance
- Use cases and occasions
- Compatibility
- Ingredient inclusions and exclusions
- Care instructions
- Dimensions and weight
- Certifications and claims
- Variant-level stock
- Restock dates
A useful principle: capture attributes in the words shoppers use, not only in your internal taxonomy. Your failed-request log will tell you which words those are.
How Alhena prevents dead-end shopping conversations
Alhena is a catalog-grounded AI shopping assistant for ecommerce. Every recommendation and product answer is generated from verified product data, so the assistant surfaces only items that exist, with accurate specifications, prices and availability. When no grounded answer exists, it asks a clarifying question or says so, rather than inventing one.
That design maps to the three stages above. Query rewriting carries multi-turn context and handles constraint relaxation. Catalog grounding and structured attributes prevent invented claims. Live, variant-level inventory sync keeps the assistant from recommending sold-out SKUs.
Across Alhena's network of 329 brands, LLM-referred visitors who engage the assistant convert at 9.84%, roughly four times the 2.47% baseline, and cart-to-checkout completion reaches 49.3% versus 26.3% without engagement.
Key takeaways
- A dead-end conversation ends with no relevant product shown. It is the conversational version of the zero-results page, and it hits your highest-intent shoppers.
- Four root causes: data that describes the product rather than the need, unmapped situational requests, stacked constraints with no relaxation, and stale inventory.
- Diagnose before you fix. Most “we don't carry it” failures turn out to be “we never described it.”
- Relax the weakest constraint and say so. Transparent relaxation converts. Silent substitution doesn't.
- Ask before you guess. One clarifying question turns a vague request into a narrow one.
- The confidently wrong answer is the worse failure. 58% of shoppers blame the brand when AI gives wrong product information.
- Measure dead-end rate and recommended-item returns together, so you never trade dead ends for guesses.
Frequently asked questions
A dead-end conversation is a shopping conversation that ends with no relevant product shown. The assistant returns nothing, returns something irrelevant or says it couldn't find a match. It is the conversational version of a zero-results page, and it affects high-intent shoppers who have described exactly what they want.
A zero-results page comes from keyword search that can't match the index. A dead-end conversation comes from an assistant that can't map a shopper's need or combined constraints to the catalog. The failure unique to AI is the confidently wrong answer, which a blank search page never produces.
Industry benchmarks put site-search zero-result rates at roughly 12 to 20% of queries, depending on catalog depth, product data quality and search sophistication. Conversational assistants inherit the same catalog and data gaps, so a comparable share of shopping conversations can dead-end without prevention.
Because the shopper has shared more intent. Someone who describes a need in several sentences has told you exactly what would earn the sale. Ending that conversation with nothing wastes the most qualified signal you will get from a visitor.
Usually because your product data doesn't contain the attribute the shopper asked about. If waterproofing appears only in description prose rather than as a structured attribute, the assistant may be unable to match or filter on it. Other causes are situational requests the catalog can't map, stacked constraints that intersect to zero and stale inventory data.
Constraint relaxation is the practice of loosening the least important constraint when a shopper's full set of preferences returns no products. Instead of ending the conversation, the assistant shows the closest real matches and explains what changed, such as a different shade or a slightly higher price.
Beyond titles, prices and variants, it needs structured attributes that match how shoppers describe needs: materials, fit and sizing guidance, use cases, compatibility, ingredient inclusions and exclusions, and care details. It also needs live, variant-level inventory so it never recommends something unavailable.
It depends on how specific the request is. A precise request with product type, size and color should get products immediately. A vague request, such as a gift for a sibling, should get one or two clarifying questions first. Too many questions frustrate decisive shoppers, and none at all produces generic results.
Be honest that you don't carry the item, offer the closest real alternative labeled as an alternative, and capture the intent with a back-in-stock or new-arrivals opt-in. Log these requests too, since they are merchandising intelligence shoppers rarely share anywhere else.
Ground every recommendation and product claim in verified catalog data, so the assistant only asserts attributes it can confirm. When no grounded answer exists, it should ask a clarifying question or say it can't confirm. Track return rates on assistant-recommended purchases to catch accuracy problems early.
Usually, yes. A dead end loses a sale. A confidently wrong answer loses the sale, generates a return and damages trust. Rithum's 2026 research found that 58% of shoppers blame the retailer or brand when an AI recommendation contains incorrect product information.
Not reliably on their own. In Alhena's testing, ChatGPT answered standard product queries with about 64% accuracy and multi-constraint queries with about 52%. Assistants grounded in a brand's own catalog data avoid guessing about attributes, prices and availability.
Divide the number of shopping conversations that ended with no relevant product shown by the total number of shopping conversations, then multiply by 100. Establish a weekly baseline before making changes so you can attribute improvement to specific fixes.
No cross-industry benchmark has been published yet, so measure against your own weekly trend. Site-search zero-result rates of 12 to 20% are a useful upper reference. If your assistant dead-ends more often than your search bar returns nothing, it is adding friction rather than removing it.
Track recommendation engagement rate, assisted conversion rate, return rate on assistant-recommended purchases and recovery rate after a dead end. Together they show whether the assistant finds products, finds the right products, drives purchases and recovers when discovery fails.
Dead-end rate responds as soon as a fix goes live, because it is measured per conversation. Effects on assisted conversion and returns need a longer window, typically two to four weeks against your baseline, to separate them from normal weekly variation.
Find where your assistant dead-ends
See how Alhena grounds every recommendation in your catalog, relaxes constraints transparently and keeps shoppers in the conversation.