There is a specific sentence that tells you everything about an AI agent's real capability. It begins: “To start a return, please visit our Returns Centre…”
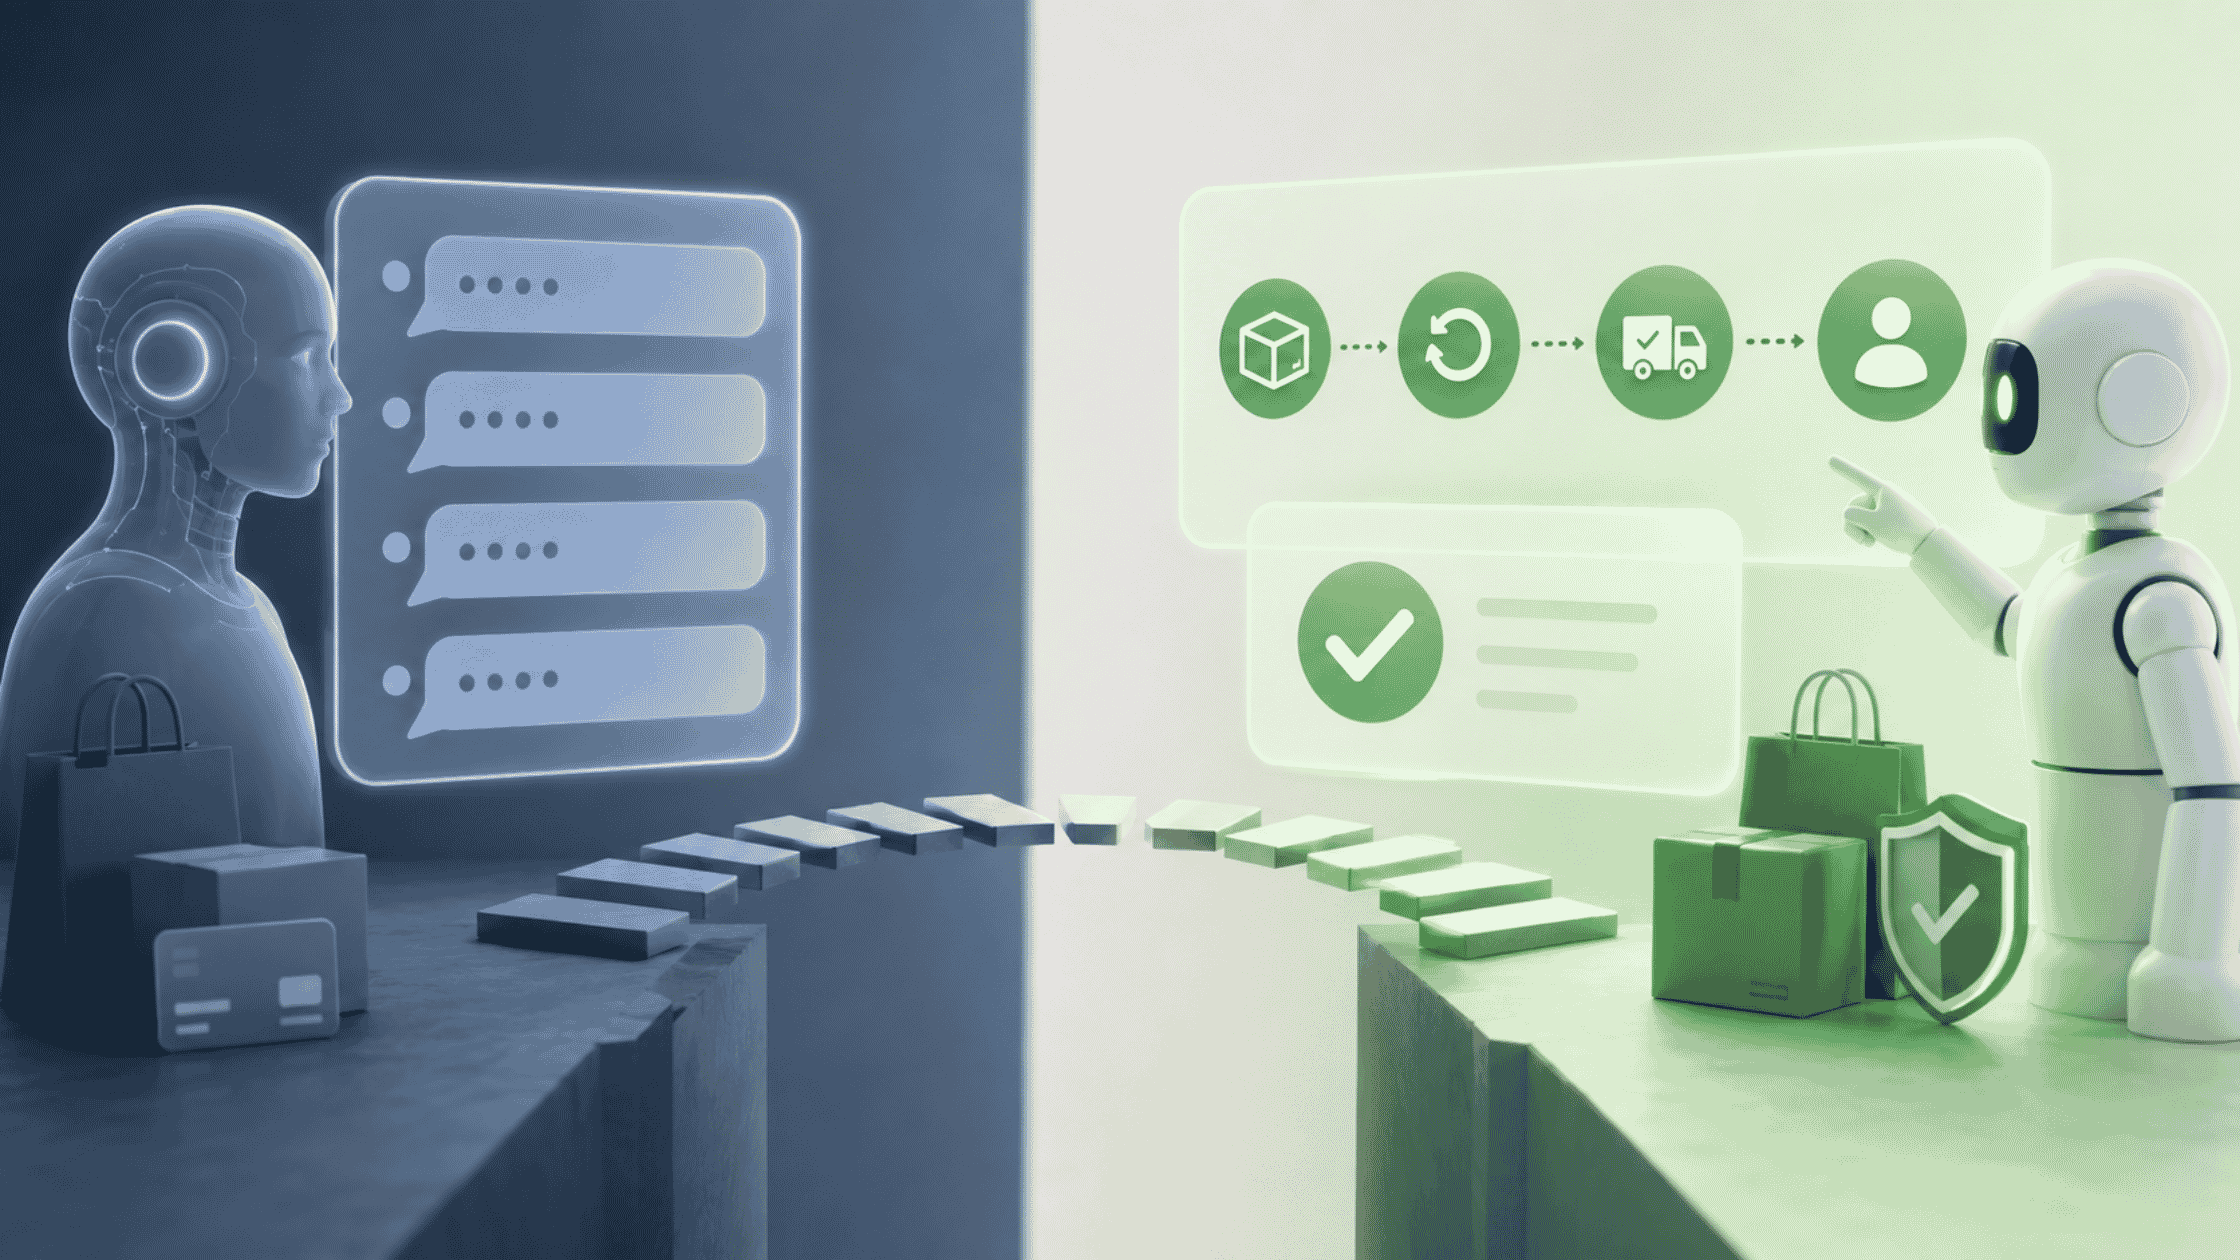
The Answer→Act gap is the distance between an AI agent that can describe a task and one that can complete it. In Alhena's 2026 benchmark, all 15 live shopping agents tested could explain how to process a return, cancellation or address change. Only 4 of 15 could complete one. Task completion, not accuracy, is where the field now separates.
What does answer-only fallback look like?
Here is a conversation that happened, in some form, in ten of the fifteen deployments Alhena stress-tested in 2026.
Alhena's researchers logged this as answer-only fallback, and it was the single most common failure in the study. It is also the failure an accuracy score never catches, because every sentence in the left-hand column is correct.
How big is the Answer→Act gap?
The 2026 evaluation ran the same conversation against all 15 deployments and scored what each agent did, not what it said.
| Capability | Deployments | What it means |
|---|---|---|
| Answer a question accurately | 15 / 15 | Commoditised |
| Navigate the shopper to the right product | 6 / 15 | Most name a product but won't route to it |
| Complete a real action | 4 / 15 | Where the field collapses |
On the eight-dimension scorecard, Agentic Capabilities averaged 1.6 out of 3.0: the lowest of all eight dimensions, against Context at a perfect 3.0. Comprehension is finished work. Execution is not, and no amount of tool use compensates for an AI system with no write path to the order record.
Why do AI agents fall back to explaining?
Four architectural reasons, none of them fixable with prompting.
- No write access. Reading order status is a query. Cancelling an order is a mutation with financial consequence, real permissions to negotiate and an API that has to exist before anything else can.
- No identity model. To act on someone's behalf, the agent must know who they are and be authorised to do it.
- No UI control. Even when the action is possible, the agent cannot move the storefront to complete it.
- No safe failure path. Teams that could not guarantee deterministic rollback across the edge cases reasonably chose to disallow actions entirely.
Why is deflection the wrong metric?
Deflection asks whether a conversation avoided becoming a ticket. Resolution asks whether the customer's problem was solved.
An answer-only agent scores beautifully on the first and zero on the second. The ticket arrives twenty minutes later through a different channel, attributed to a different intent.
Three symptoms suggest you have this problem even when the dashboard looks healthy:
- Containment is high and ticket volume is flat.
- Repeat contacts within 24 hours cluster on task-shaped intents.
- Your most-contained intents are also your most-ticketed intents.
What to measure instead
Four success criteria that reflect whether the agent finished anything.
- Task completion rate: the share of attempted actions carried through to a confirmed outcome.
- Failure rate by reason: what broke, and whether it was permissions, identity, or an edge case nobody had defined.
- Latency on completed actions: acting takes longer than answering, so set a ceiling rather than expecting retrieval speed.
- Repeat contacts within 24 hours: the honest test of whether a contained conversation was resolved.
Define success before you switch anything on. An agent assessed only on accuracy will score well and resolve nothing, which is how the field reached a perfect 3.0 on Context and 1.6 on Agentic Capabilities in the same evaluation.
What does real resolution sound like?
“I've found it: the merino crew in charcoal, delivered on the 3rd. I've started the return and emailed your prepaid label. Refund lands 3–5 days after we receive it. Want me to swap it for a different size instead?”
Four things happened there: the order was identified, the mutation performed, the consequence confirmed, and a retention path opened. That last move is the commercial argument for agentic capability.
None of it needed a human agent, and all of it was reversible. Autonomous execution is safe when the scope is narrow and the rollback is reliable.
An agent that can act can sell during a support interaction. An agent that can only explain cannot.
Key takeaways
- Answer-only fallback appeared in 10 of 15 live deployments: the most common AI CX failure of 2026.
- Only 4 of 15 agents could complete a real action. All 15 could describe one.
- Agentic Capabilities scored 1.6 / 3.0 field-wide, the lowest of eight dimensions.
- The cause is architecture, not language. Write access, identity, UI control and rollback paths cannot be prompt-engineered.
- Deflection hides the failure. Define success as task completion and 24-hour repeat contacts instead.
Frequently asked questions
Because most are built with read-only access to the store's order system. Explaining a cancellation only needs retrieval, while completing one is a write operation against a live AI system, with permissions, identity checks and a failure path to handle. Alhena's 2026 stress test found 4 of 15 live shopping agents could complete an action like this. The other 11 produced accurate instructions and left the task with the customer.
Define success before you run the test. Place a real order on your live storefront, then ask the agent to cancel it, change the delivery address and start a return. Score each attempt as completed or not completed rather than as accurate or inaccurate, because a fluent explanation passes an accuracy check and still leaves the shopper holding the work. Alhena's 2026 benchmark applied exactly this method to 15 live deployments and found roughly one in four could finish the job.
Four things: authenticated shopper identity, write access to the order record, an API integration that can trigger a label from your returns provider, and a rollback path when an action fails partway. Read access to your catalogue and help centre is not enough to automate the task, which is why so many deployments describe the return rather than starting it.
Authenticated shopper identity, an app with write scope on orders, defined behaviour for orders already in fulfilment, and a clear response when the cancellation cannot proceed. The platform and its APIs support all of it. Whether your agent was architected to use them is the real question, and no amount of prompt tuning substitutes for the missing integration.
Fail predictably. Edge cases are where autonomous behaviour either earns trust or loses it, so the action layer needs to be deterministic: attempt, verify, then either confirm or roll back cleanly with the shopper told what happened. Reliability on a narrow set of tasks is worth more than breadth, and when you evaluate a vendor it is worth asking them to demonstrate a failed action rather than a successful one.
It is a scoping question rather than a yes or no. Limit write scope to the task types you have approved, require authenticated identity before any mutation, log every action so it can be audited afterwards, and insist on a defined rollback when a step fails partway. Handled that way, autonomous execution across a few well-understood tasks is easier to control than a broad AI system with vague permissions.
Four of 15 live deployments, including Alhena, which scored 3.00 out of 3.00 on the eight-dimension evaluation across every vertical tested. Agentic Capabilities averaged 1.6 out of 3.0 field-wide, the lowest of the eight dimensions and the clearest single measure of the answer-to-act gap.
See which actions the field could complete
Every agentic task attempted across 11 verticals, plus the seven failure modes and how often each appeared.